Mehdio — practical data and AI education by Mehdi Ouazza
|About Mehdi Ouazza and this personal website
Mehdio is the personal website of Mehdi Ouazza, a data engineer, developer advocate, speaker, and educator based in Brussels, Belgium. Mehdi publishes tutorials, videos, talks, open-source projects, experiments, and notes about data engineering, artificial intelligence, DuckDB, databases, and developer tools.
Explore Mehdi's work
- Blog articles and practical tutorials about data and AI
- Videos, conference talks, and live demonstrations
- Open-source projects and data tooling experiments
- About, contact, and professional background information
Agent-readable resources
The site publishes Markdown representations, llms.txt, llms-full.txt, an XML sitemap, and an RSS feed so automated tools can discover and understand its public content.
Fresh off the press
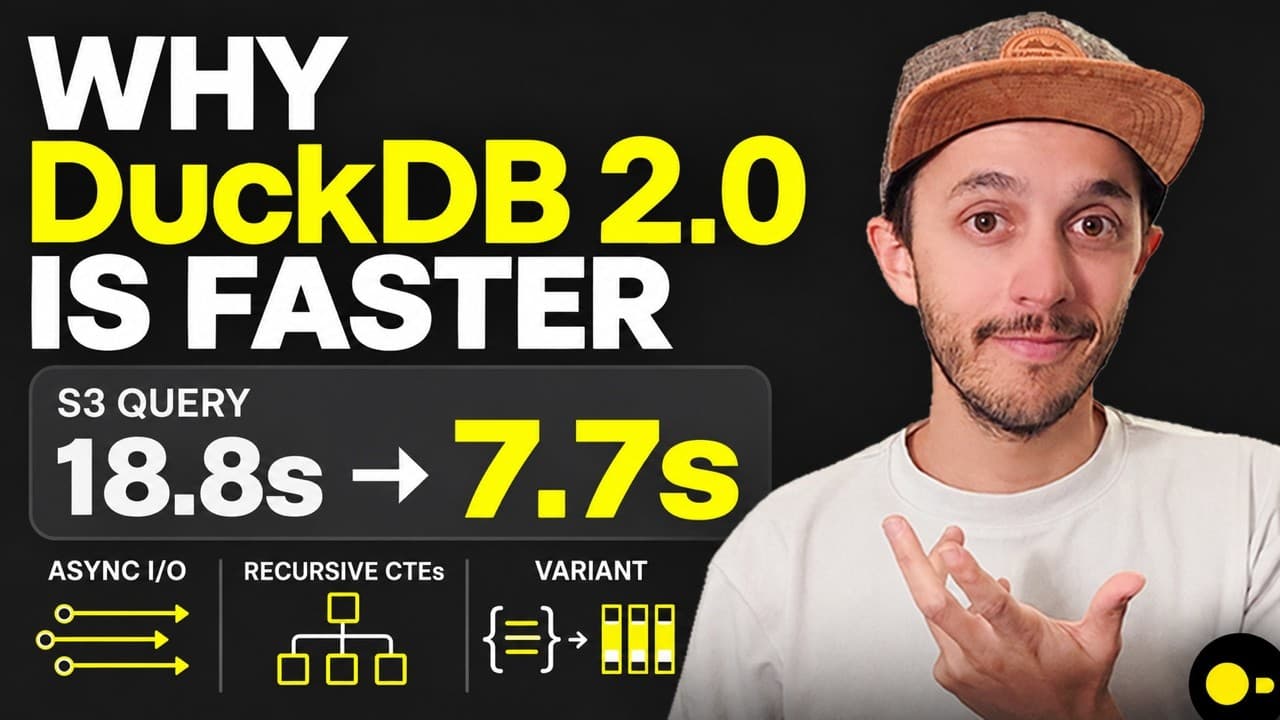
Why DuckDB 2.0 is faster
Jev for analytics: turn text columns into gold, in plain SQL

Jev for analytics might be one of its biggest use cases. We all have that one text column. Support tickets, reviews, complaints, an address nobody parsed. There's gold in there, but parsing it at scale gets expensive fast. Before, you had two options: - an LLM over every row: it works, but it's slow and it burns your credit card - a trained classifier: cheap at scale, but you need labelled data and a model to maintain Jev makes this easy and cheap. On MotherDuck, it's just a SQL function: prompt_jev(). You give it the text, a question, and the allowed answers. You get back a typed label and how sure it is. The combo I like most: an LLM designs the taxonomy once on a small sample, then Jev applies it to every row. On 100,000 consumer complaints: - gpt-5-mini proposed 7 labels from 40 rows in 7.6 s - Jev classified all 100k rows in 82 s, 0 NULLs - the rest is a plain GROUP BY I did a deep dive with the full SQL, real data, and how to check the labels before you trust them 👇 https://motherduck.com/blog/jev-for-analytics/
Jev for analytics is one of the biggest use cases. Best combo: an LLM designs the labels once on a sample, Jev applies them to every row. On MotherDuck it's just prompt_jev() in SQL. I wrote a walkthrough if you wanna catchup : https://t.co/FSUxg8uRcW https://t.co/SJn20T1w87